Read paper ICCV Workshops proceedings Code on GitHub Slides
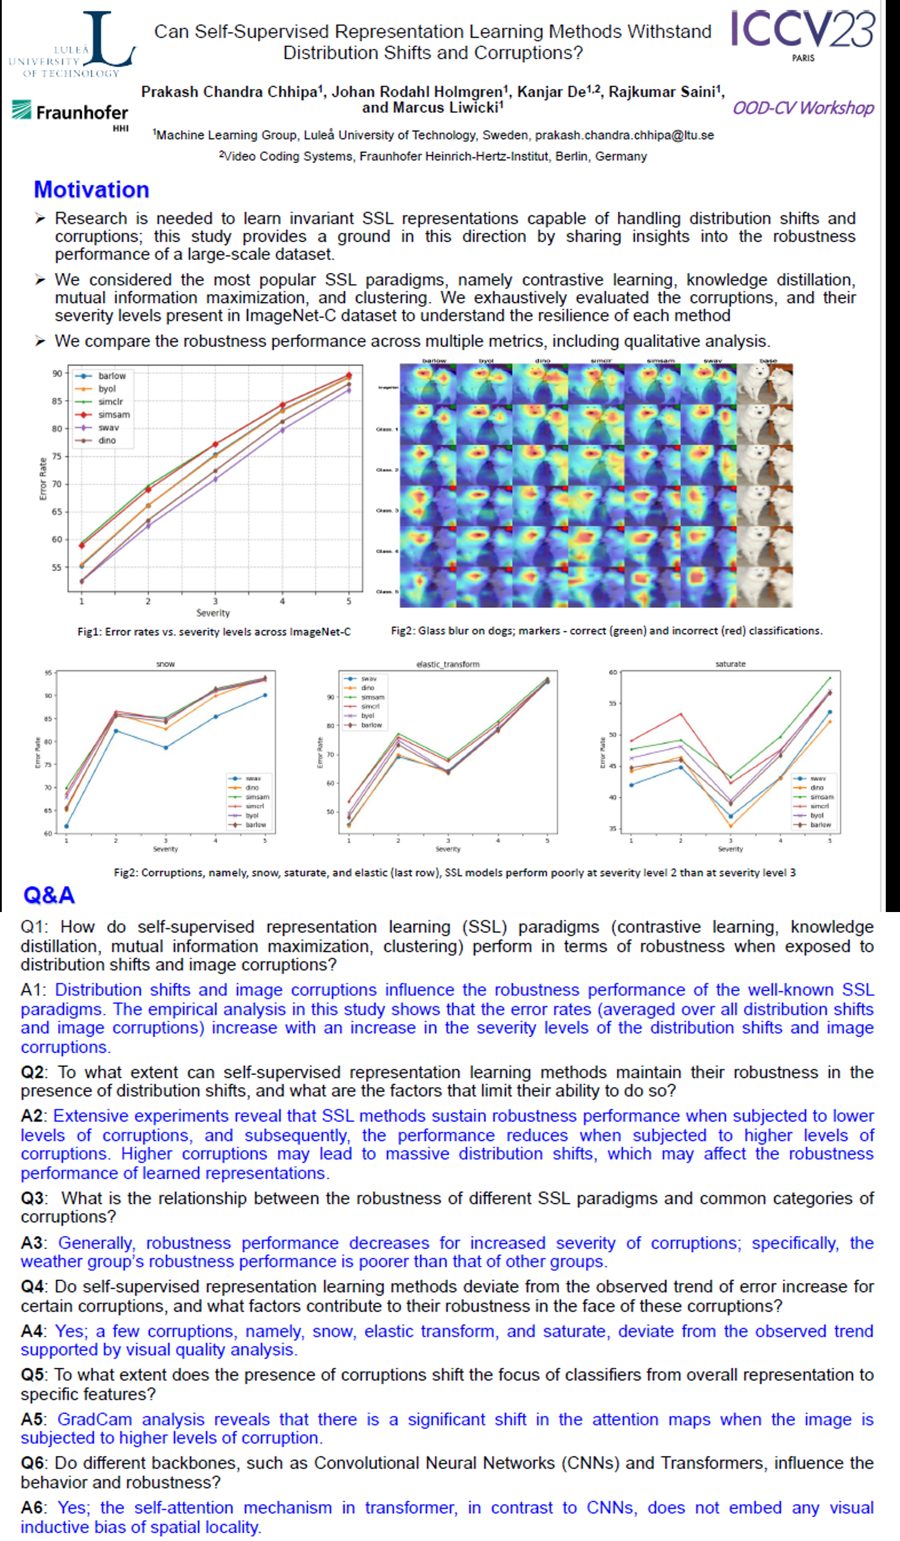
Self-supervised methods are often assumed to learn invariant, robust representations. This work tests that assumption under real distribution shift — and finds that robustness drops sharply as shifts and corruptions grow more severe.
Presented at the Out-of-Distribution Generalization in Computer Vision (OOD-CV) workshop at ICCV 2023, Paris.
The question
Self-supervised learning learns from the structure of data itself, without human labels. Its main paradigms — contrastive learning, knowledge distillation, mutual-information maximization and clustering — are widely credited with learning invariant representations. But are those representations actually robust when the input distribution shifts, or when images are corrupted the way real cameras corrupt them?
What we did
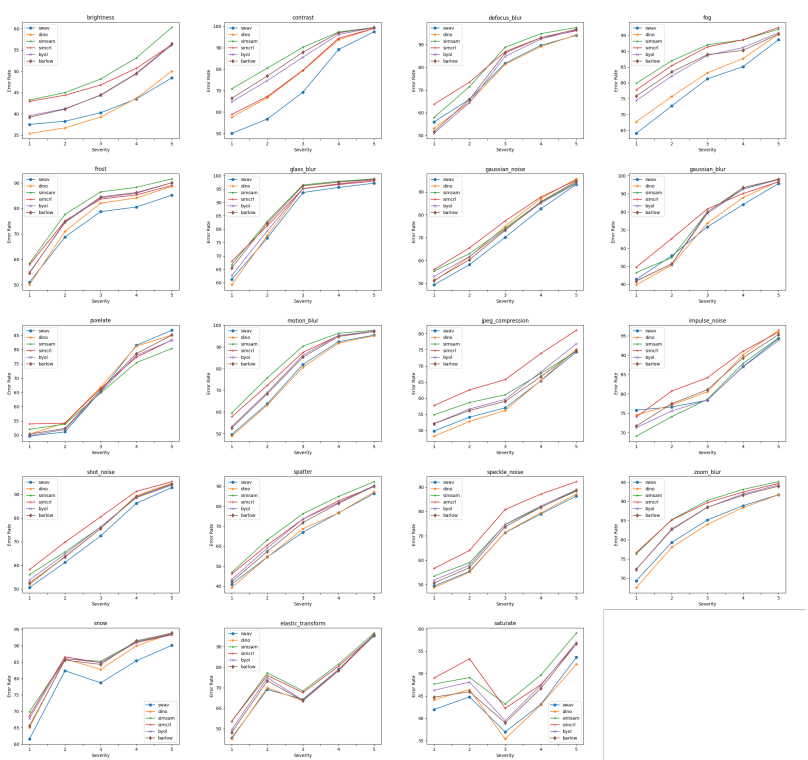
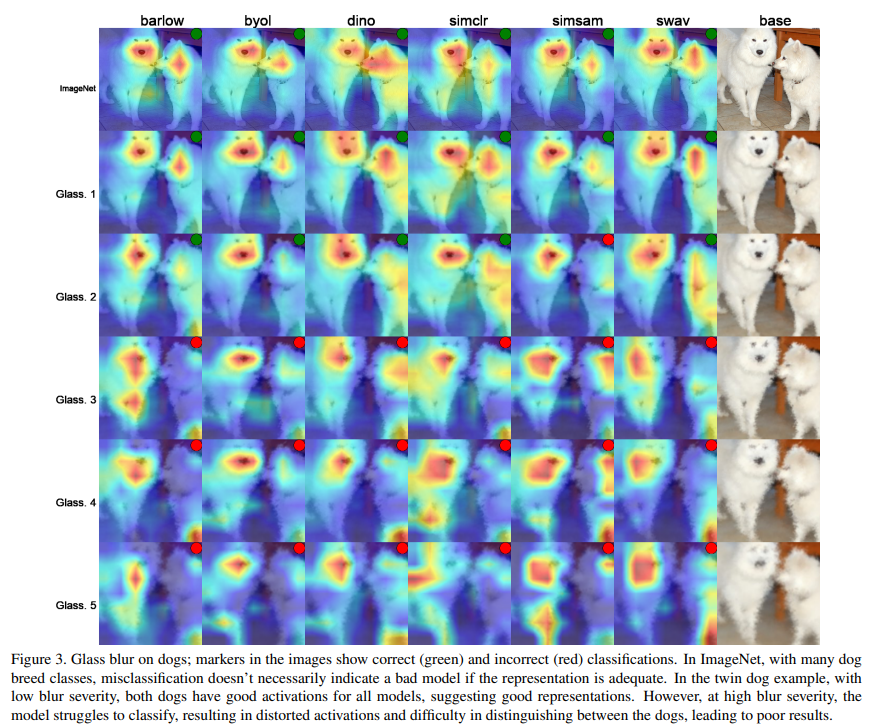
We ran a systematic robustness study of six self-supervised methods on ImageNet-C, across every corruption type and every severity level, measuring mean corruption error and inspecting class activations.
- SimCLR — contrastive learning
- SimSiam and BYOL — siamese and bootstrap methods
- Barlow Twins — redundancy reduction
- SwAV — clustering
- DINO — self-distillation with vision transformers
What we found
There is a clear relationship between how severe a shift or corruption is and how much the learned representations degrade. At higher severities, robustness falls significantly across all paradigms — no method is immune.
Why it matters
Benchmarks on clean data overstate how self-supervised models will behave in deployment. The study argues that safety and robustness should be first-class objectives in self-supervised representation learning — the motivation for the later work on Möbius-MPD and ASTrA.